Free cookie consent management tool by TermsFeed Generator

About Us: Who We Are, Our Values &Asia-Pacific Footprint

AI infrastructure services

AI Infrastructure Delivery and Operations

Advange provides full-stack operations and maintenance for AI data centers—from compute cluster deployment and high-speed interconnects to platform operations, critical facilities, and continuous improvement.

24/7 monitoringContinuous AIDC operations center
GPU · Server · NetworkOne operational view across the stack
Remote and on-siteService desk, local engineers, and L2 experts
Multi-region deliveryStructured support across Asia
The challenge

AI infrastructure fails across layers—not in isolation.

GPU health, server configuration, high-speed fabrics, job schedulers, and critical facilities are tightly connected. When each layer is operated separately, diagnosis slows down and capacity is lost.

AIDC operations

Visibility is only useful when it leads to coordinated action.

Cross-layer faults

GPU, server, fabric, storage and facility conditions can influence the same incident.

Limited performance baselines

Without unified telemetry and workload baselines, underutilization and performance degradation remain hidden.

Fragmented response

On-site teams, remote engineers, OEM support and service management need one escalation path.

Facility and safety risks

Power, cooling, fire protection, access, and emergency readiness must support uninterrupted computing operations.

Operating principle:Connect infrastructure, platform, facilities, and people as one service—not as separate handoffs.
Service scope

One operating model, from cluster deployment to facility reliability.

The service scope is modular. Customers can begin with a focused requirement or combine the layers into a full-stack AIDC operating service.

01 / Consulting

Consulting services

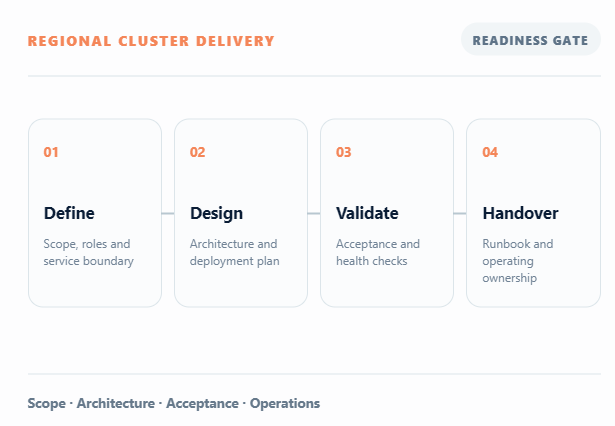
Prepare AI compute infrastructure for deployment, acceptance, and stable operations across Southeast Asia.

Compute cluster architecture and deployment planning

Acceptance testing, health checks, and readiness review

Operating scope, roles, and support model definition

Regional AI cluster delivery stages
02 / Control

Data Protection and Access Control

Protect operational data and establish consistent controls around access, interfaces, and service activity.

Network security and data protection

Supplementary IT services

Standardized O&M interfaces and access controls

03 / Observe

Platform and application

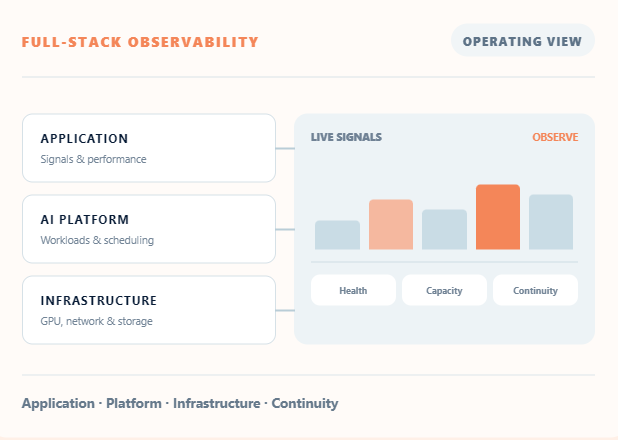
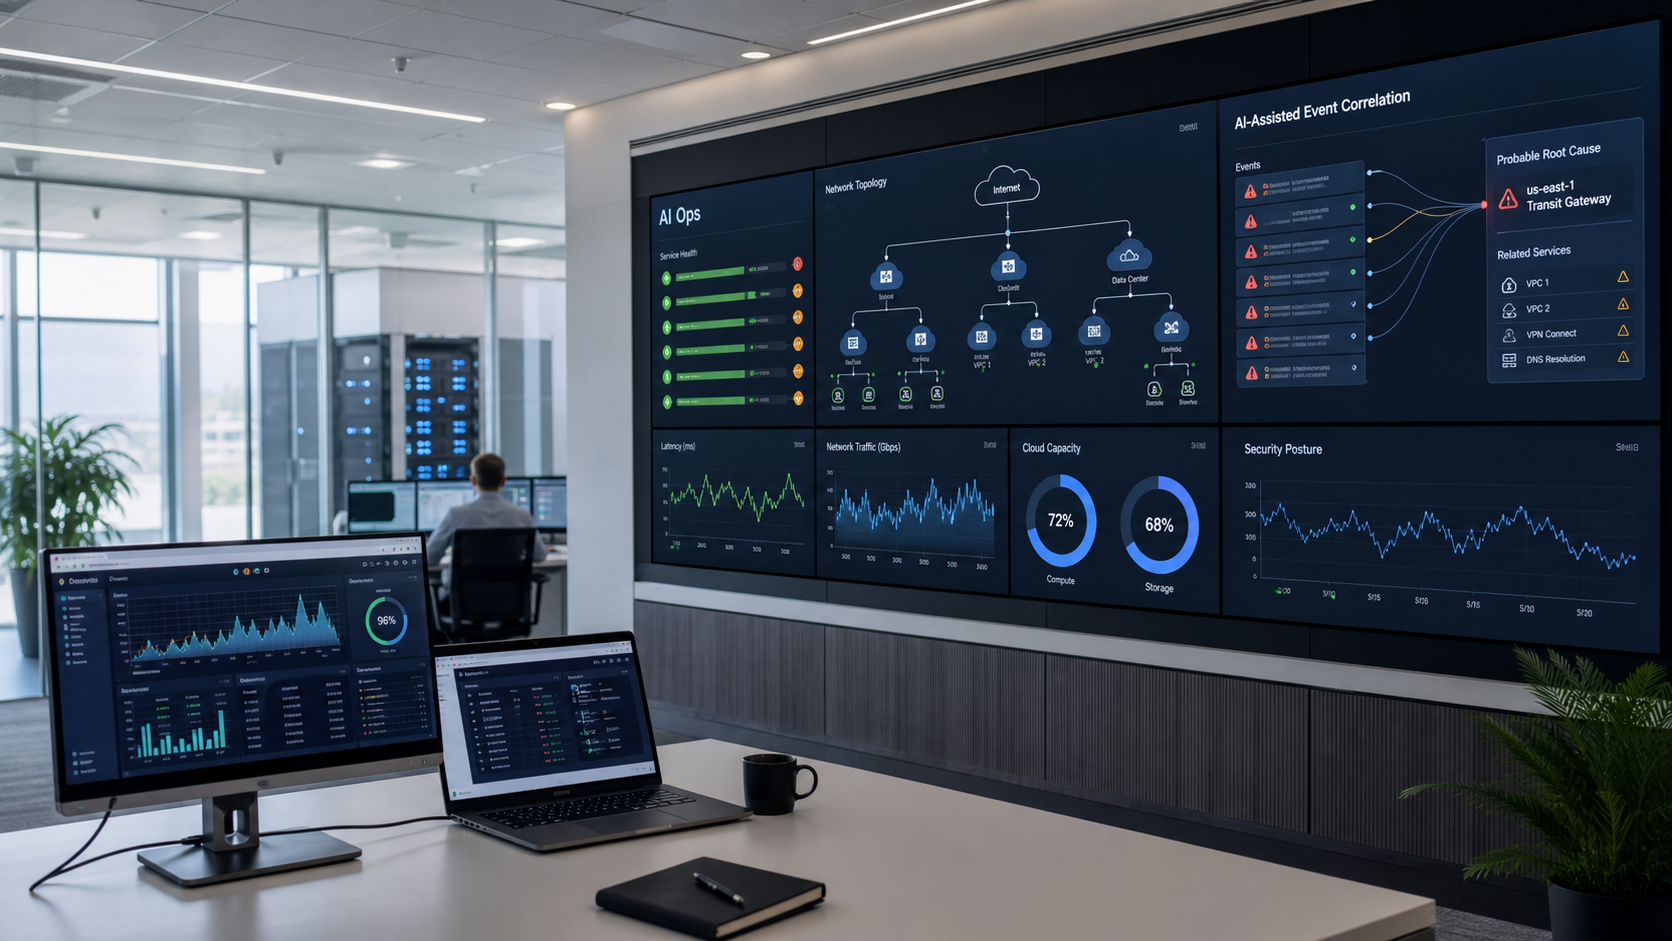
Operate the AI platform with end-to-end observability and continuous workload performance monitoring.

AI platform operations and maintenance

Business continuity assurance

Full-stack observability and application optimization

Full-stack observability across applications, the AI platform, and infrastructure
04 / Compute

Compute cluster

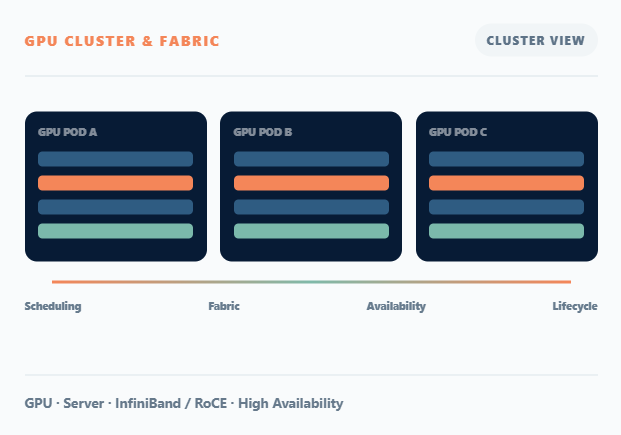
Keep GPU clusters available and efficient throughout deployment, scaling, daily operations, and fault recovery.

Cluster deployment, delivery, and lifecycle operations

Compute scheduling and utilization optimization

Predictive maintenance and high-availability assurance

InfiniBand / RoCE operations and optimization

GPU racks connected by a high-speed network fabric
05 / Facility

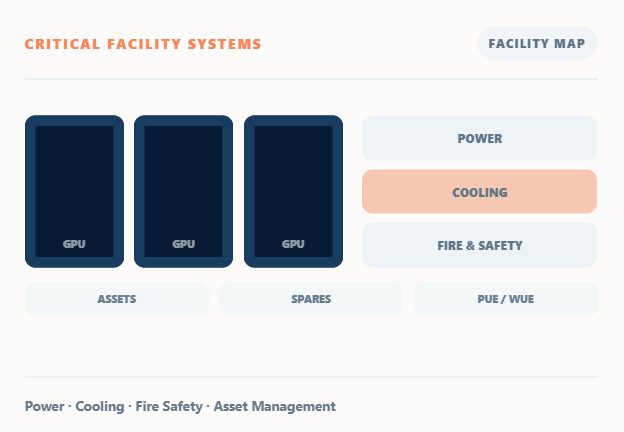
Facility infrastructure

Maintain the physical environment that keeps high-density AI compute safe, available, and energy efficient.

Critical power, cooling, fire protection, and low-voltage maintenance

Green operations, including PUE / WUE tracking

Asset, spare parts, and emergency readiness management
Data center racks and critical facility systems
Designed for
Industry end customersAI computing service providersIDC service providers
Operating model

A connected delivery team turns monitoring into action.

The AIDC Operations Center combines continuous monitoring, local delivery, service governance, and technical expertise within one operating model.

01 / Monitor

24/7 AIDC monitoring center

Unified telemetry, alert correlation, work-order creation, scheduling, and access coordination.

02 / Deliver

Service desk & on-site team

Business-hours request handling, physical inspection, replacement, cabling, validation, and recovery.

03 / Resolve

L2 experts & service management

Advanced diagnosis, OEM coordination, performance tuning, quality control, and continuous improvement.

Standard process library

One Governance Model for Every Service Action

Clear triggers, roles, approvals, records and closure criteria make cross-team execution consistent.

01

Incident management

Identify, classify, prioritize, diagnose and restore.

02

Escalation

Functional and management escalation with clear ownership.

03

On-site support

Visit readiness, execution records and completion checks.

04

RMA

Fault validation, packing, replacement and asset updates.

05

Change request

RFC, approvals, implementation and rollback control.

06

Access request

Role-based approval, time limits and special-case handling.

07

Knowledge & SOPs

Versioned runbooks, known issues and lessons learned.

Service assurance

Rapid response is designed into the operating model.

Monitoring, predefined scenarios, remote-first resolution and parallel on-site execution reduce the time between detection and recovery.

24/7Monitoring coverage

Continuous communication and operational visibility.

10 minMTTD target

95% target for early detection and alert verification.

2 hrMTTR target

80% target supported by parallel remote and on-site action.

15 minUpdate cadence

Updates during critical incident response.

01

Detect

Collect telemetry across GPU, server, network and facilities.

02

Diagnose

Correlate alerts and isolate hardware, network or software causes.

03

Resolve

Execute remote recovery, on-site action, RMA or OEM escalation.

04

Improve

Update runbooks, knowledge, training and performance baselines.

Service transition

Start with control. Scale with confidence.

Transition establishes the technical baselines, tools, responsibilities and operating procedures required before live service begins.

Build readiness before taking operational responsibility.

Advange aligns the service boundary with the customer, validates the environment and prepares the delivery team before entering steady-state operations.

01

Discover & baseline

Inventory, topology, workload, facility and current-performance review.

02

Design the operating model

Scope, roles, escalation, access, SLAs, workflows, and reporting.

03

Prepare & validate

Monitoring, tools, runbooks, knowledge transfer, training and scenario drills.

04

Operate & improve

Controlled go-live, performance review and continuous optimization.

Why Advange

Technical depth, local delivery, and OEM collaboration.

The service combines full-stack AI infrastructure capabilities with multilingual operations and direct collaboration across the technology ecosystem.

01

Full-stack AI infrastructure capabilities

End-to-end operations covering GPU deployment, cluster health, network performance, platform monitoring, and facility reliability.

Reported outcome (source required): 30% faster incident resolution and more than 20% higher resource utilization.

02

Native multilingual support

24/7 support designed for English, Malay and Chinese operating environments and cross-border delivery teams.

Reported outcome (source required): 50% more efficient cross-border collaboration.

03

OEM strategic partnerships

Deep collaboration with manufacturers such as Supermicro and ASUS, supported by pre-staged spares and certified AI solutions.

Reported outcome (source required): Four-hour on-site response and up to 70% lower mean time to repair (MTTR).

AI infrastructure operations

Build an operating model
for your AI infrastructure.

Discuss your current environment, service boundary and availability requirements with the Advange AIDC operations team.

Free consultation and quote

We will contact you promptly.

The information you submit will be used only to respond to your enquiry and will not be disclosed to third parties except as described in our Privacy Policy.

Your message has been sent.

Thank you for your enquiry. We will contact you promptly.